译文
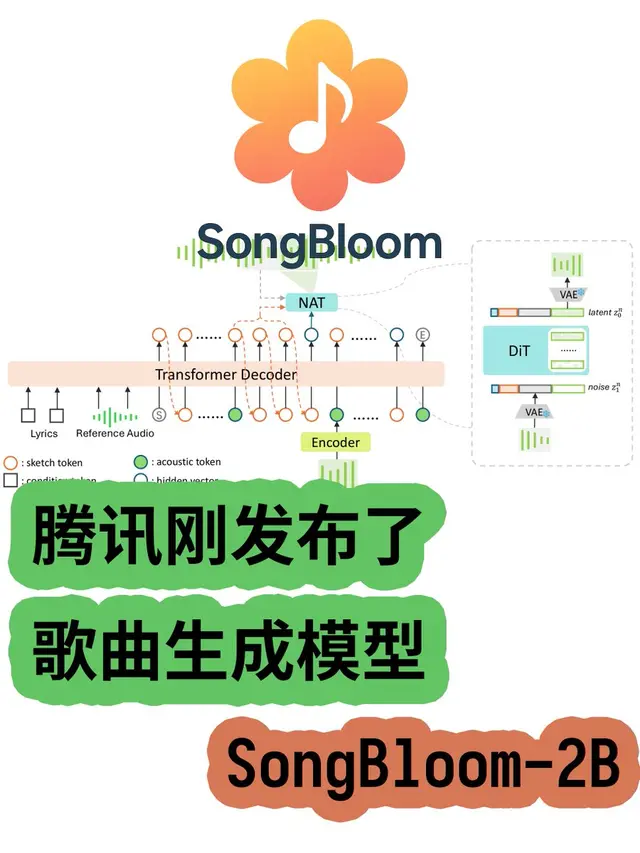
Tencent has just released an improved version of the song generation model SongBloom-2B, called songbloom_full_240s! It supports music generation up to 4 minutes in length.

At the same time, they have also updated the generation framework, also known as SongBloom. From the introduction, it is an autoregressive diffusion model, with the official saying it has both the precision of diffusion models and the extensibility of language models. The internal generation will gradually expand from short music segments to complete pieces of music.

This model requires inputting lyrics and reference audio in a specific format to clone the song style. Additionally, the model has also been released to the personal space on huggingface. There is no demo space, so I don't have an especially convenient way to record a demo for everyone. Those interested can download the model and try running it themselves, as it is only 2B in size and can be run on a CPU.

Address:
 桃子AI画廊Tao Image Gallery