提示词
4 prompting mistakes that are ruining your GPT Image 2 + Seedance 2.0 output quality right now:

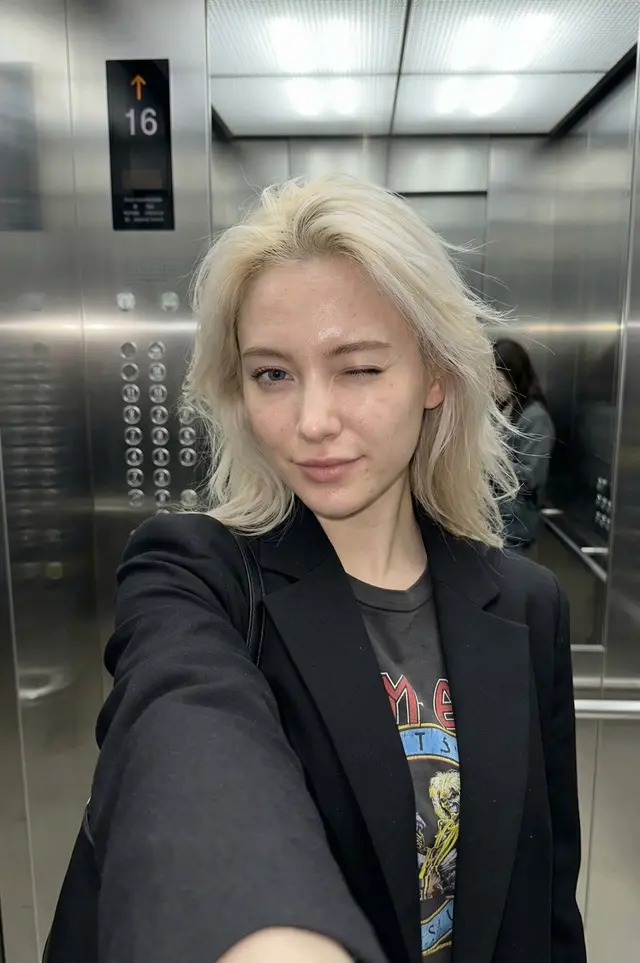
1/ you're feeding Seedance a GPT Image 2 reference image that was generated without specifying the interaction between the character and the product

if your reference image shows the character standing next to the product rather than holding it, applying it, or actively engaging with it...

then Seedance has no visual foundation for the product interaction sequence and defaults to generating awkward static holding poses that look robotic

you should generate your GPT Image 2 reference with the exact product interaction you want Seedance to animate instead

if the script calls for the character to apply a cream to her cheek, generate a reference image showing that specific gesture at that specific moment

Seedance animates what the reference shows, not what your text prompt describes when the two conflict

2/ you're not generating enough reference variants before picking the one you feed into Seedance

if you generate 1 GPT Image 2 character reference and run it straight into Seedance, you're accepting whatever demographic, expression, and visual quality happened to come out of that single generation

generate 6 to 8 variants from the same prompt and select the strongest 2

the difference between the weakest and strongest variant from a single prompt is often the difference between output that passes the real person test and output that doesn't

3/ you're generating your GPT Image 2 product shots and your character references under completely different lighting conditions and then wondering why the assembled reel looks off

Seedance is compositing visual inputs that were generated separately.

if your character reference has warm morning light from the left and your product shot has cool overhead lighting, the mismatch creates the subtle visual incoherence that viewers register as "something feels wrong" even when they can't articulate why

generate all reference assets in the same lighting environment before running anything into Seedance

4/ you're using GPT Image 2 for the character reference but still writing the Seedance prompt in generic language instead of updating it to reflect what the reference actually shows

the reference image locked in a specific scene environment, a specific lighting condition, and a specific character aesthetic

your Seedance prompt should describe those same specifics back to the model rather than using generic placeholder language like "natural lighting" or "realistic setting"

if your GPT Image 2 reference shows a woman in a marble bathroom with soft morning light from the left, your Seedance prompt should say exactly that

the more precisely your prompt matches what the reference image shows...

the more coherently Seedance animates from it

- adrian
 桃子AI画廊Tao Image Gallery